
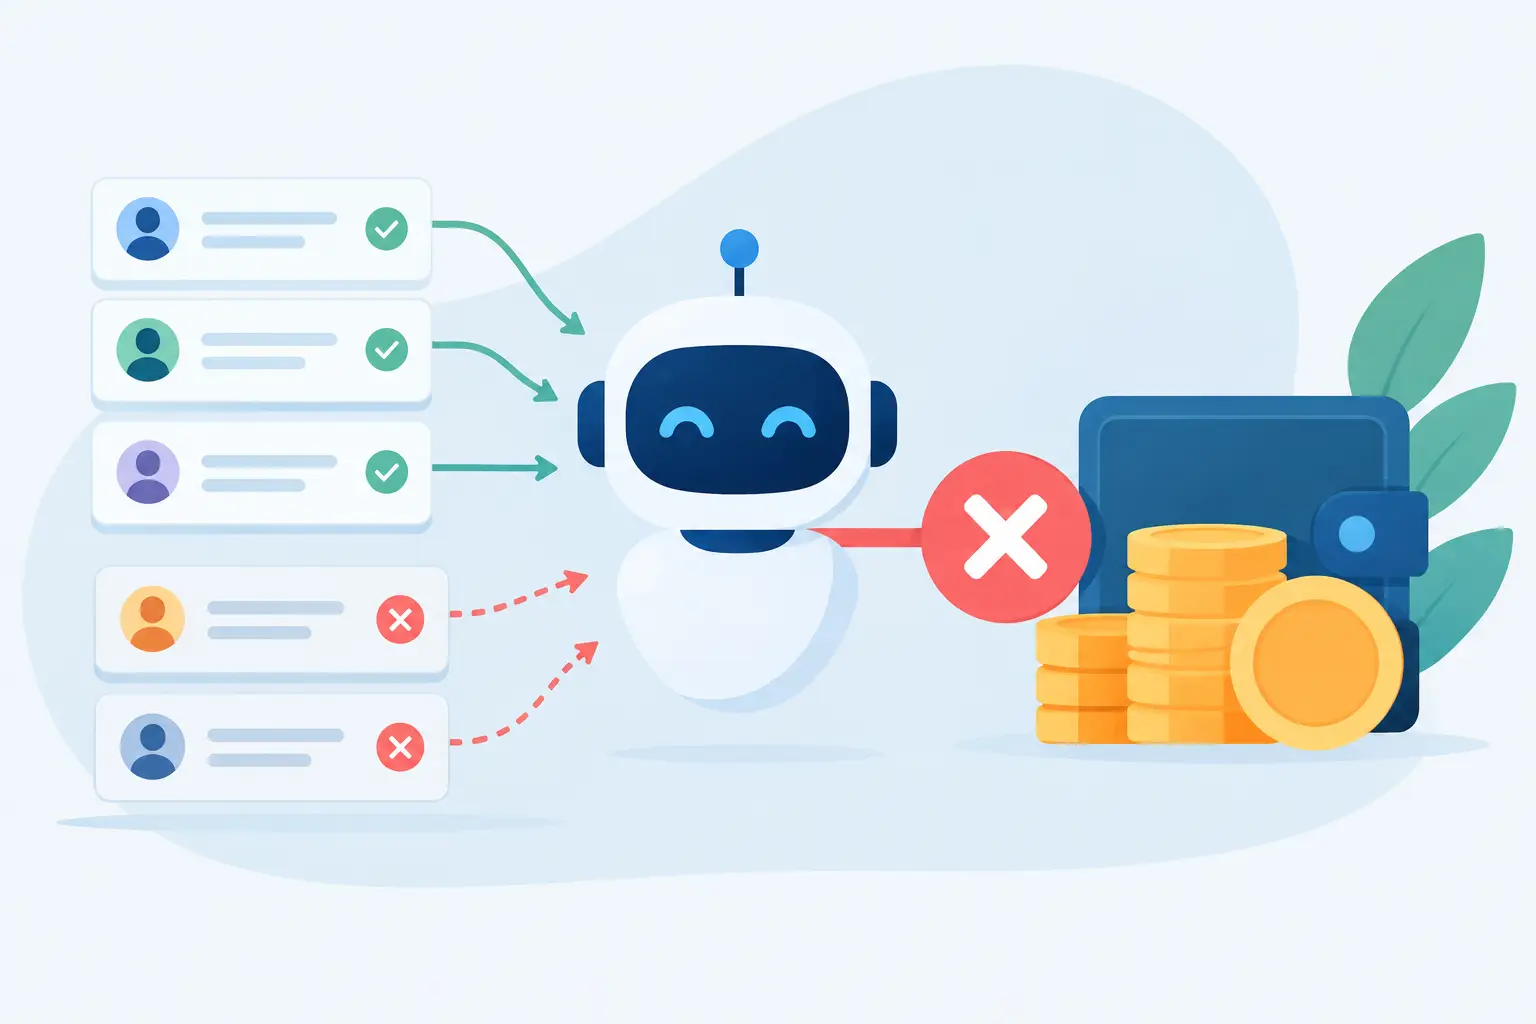
A finance alert that arrives after a costly batch has completed is useful for reporting, not control. When an internal copilot, customer-facing assistant or automated workflow can continue calling models after its allocation is exhausted, the budget is merely a dashboard number. The practical question is: can LLM budgets block requests before further spend occurs?
Yes. A hard LLM spend cap can block a request at the AI gateway and return a 429 response once the relevant budget is exhausted. That changes a budget from an observation tool into an enforceable operating limit. It also creates a decision that engineering, FinOps and security teams can reason about: this request was not sent to a provider because it would have breached an approved spend boundary.
Can LLM budgets block requests without changing application logic?
They can, provided enforcement sits on the request path rather than in a separate reporting process. A governed gateway is positioned between the application and the model providers. Every call passes through one controlled point, where the platform can account for usage and apply the relevant cap before forwarding a request.
For teams already using an OpenAI-compatible client, the integration does not need an application rewrite. The client continues to make chat completion requests; the endpoint and API key change. Business logic stays byte-for-byte identical.
import os from openai import OpenAI
client = OpenAI( api_key=os.environ["ROUTEUR_KEY"], base_url="https://api.routeur.ai/v1" )
response = client.chat.completions.create( model="auto", messages=[ {"role": "user", "content": "Summarise this support case."} ] )
With a hard cap applied through that governed doorway, a request that would exceed the available budget is blocked with a 429. The application should handle that response deliberately, just as it would handle rate limiting or a temporarily unavailable dependency. It may present a clear message to the user, defer a non-urgent job, or route the workflow into an approved manual queue.
The important distinction is that a spend cap is not a traffic-management mechanism. A blocked budget does not automatically reroute traffic to a cheaper model. Routing decisions and budget enforcement serve different purposes. Routing selects the most cost-effective capable model within defined rules and priorities; a hard cap sets the maximum permitted spend. Once that boundary is reached, the correct outcome is alerting or blocking, not silently continuing consumption elsewhere.
Why a blocked request is often the right outcome
Blocking can sound severe, particularly for product teams judged on availability. But unlimited model spend is not a neutral default. A prompt loop, a sudden increase in document size, an untested agent workflow or an exposed API key can turn a modest usage pattern into a material bill quickly.
A hard cap limits the blast radius. It gives a team time to investigate whether the increase is legitimate, whether prompts have become inefficient, or whether a route is using the intended providers and models. In regulated environments, it also supports a clearer operational story: spend limits are configured, enforced consistently and evidenced through request-level traces.
That does not mean every workload should share one global cap. A production customer support assistant, an overnight evaluation suite and an experimental internal tool have different business consequences when blocked. The right design separates them into meaningful scopes, using scoped API keys and named routes so that one team or workflow cannot consume another’s approved capacity.
For example, an organisation might apply a tighter budget to a prototype route while preserving a larger controlled allowance for a revenue-critical workflow. The goal is not to make every request equally constrained. It is to make ownership and consequences explicit.
Treat 429 handling as part of the product design
A 429 is a predictable control response, not an unexplained failure. Teams should decide ahead of time what it means for each workload.
For an interactive feature, the user experience might state that the AI service has reached its current capacity and invite the user to try again later. For an asynchronous process, a job can be paused and retried after the budget is renewed. For a high-impact internal workflow, the appropriate outcome may be escalation to an operator rather than an automated retry loop.
Blind retries are usually the wrong answer. If a hard cap is exhausted, repeatedly resending the same request adds noise without restoring available budget. Monitoring should distinguish budget blocks from provider errors, latency problems and policy blocks, because each requires a different operational response.
Budget controls work best alongside request-level policy enforcement
Cost control should not be isolated from the rest of the request lifecycle. A request that is unsafe or contains sensitive data should not reach model routing simply because there is budget available.
A disciplined request path applies prompt shielding first, then DLP, then routing, then output moderation. Prompt-injection and jailbreak shielding assesses the input before it can influence downstream behaviour. DLP can log, warn, redact or block sensitive data. When redaction is configured, the affected value is replaced with [REDACTED]; it is not tokenised for later restoration.
Only then is an eligible request routed according to the configured rules and priorities. The resulting output can be moderated before it is returned to the application. Budget enforcement belongs in this governed flow, where each request is evaluated consistently rather than relying on individual teams to add their own checks.
This ordering matters operationally. It prevents a team from treating cost optimisation as permission to send every prompt onwards. It also makes investigations more precise. If a request did not reach a provider, was it blocked by prompt shielding, DLP, a spend cap or another policy outcome? Per-request traces provide the evidence needed to answer that question without relying on inference from provider invoices.
Designing budgets that do not surprise the business
The strongest budget policies are agreed before the cap is reached. Engineering leaders, FinOps owners and product teams should define which workloads can pause, which require an escalation path and who is authorised to adjust limits. A cap that arrives as a surprise during a critical process is usually a planning problem, not a gateway problem.
Start with distinct boundaries for production, development and experiments. Development environments are valuable, but they are also where repeated test runs and unbounded prompts are easiest to overlook. Separating those workloads prevents testing activity from consuming the allowance intended for customer-facing services.
Next, align named routes with real ownership. A route such as support-assistant or document-review is easier to govern than an undifferentiated pool of traffic. It enables teams to assess spend, model selection and policy outcomes in the context of a known service rather than a generic API total.
Finally, use traces and metadata to investigate change. Metadata-only logging by default reduces unnecessary payload retention, while explicit opt-in is available where payload retention is required for an approved purpose. This balance matters for organisations handling personal, commercially sensitive or regulated information: observability should support operations without casually retaining prompts and outputs.
The trade-off: control can expose weak fallback plans
Hard caps make a failure mode visible. That is their value, but it means teams must own the customer and operational experience that follows. A cap that blocks a low-priority summarisation queue may be entirely acceptable. The same cap on a workflow supporting time-sensitive decisions may need a larger allocation, closer monitoring and a documented human fallback.
There is also a trade-off between a very tight limit and normal variation in usage. LLM spend is affected by input length, output length, model choice and request volume. Set caps using observed workload behaviour and a clear risk tolerance, then review them as the product changes. A budget should be firm enough to prevent uncontrolled exposure while allowing the service to operate as intended.
routeur.ai provides one governed doorway for these decisions: routing, security controls, data protection, hard spend caps and traces can be applied at the request layer without changing application business logic. That centralisation is particularly useful when several teams use different providers but need consistent policy enforcement and auditable control.
A budget that only reports overspend tells you what happened. A hard cap that returns a 429 determines what is allowed to happen next. The useful next step is not simply setting a number: it is deciding which requests your organisation is genuinely prepared to stop, and designing the response before that boundary is tested.